Bridging Domains for Automatic Post-Editing: A Classifier-Guided Multi-Domain Adaptation Framework
Abstract
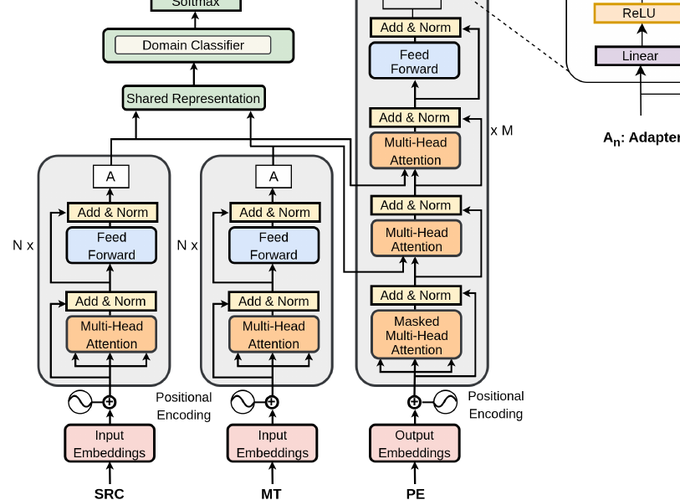
Automatic Post-Editing (APE) is a widely studied approach for enhancing the output quality of Neural Machine Translation (NMT) systems. While most prior work has focused on general-purpose APE, the potential of domain-specific APE, such as for personalized or specialized content, remains underexplored due to the scarcity of domain-labeled training data. In this work, we investigate domain adaptation for APE using adapter-based methods. Our proposed multitask learning-based domain adaptation framework includes the use of a domain classifier to get a weighted combination of parallel domain-specific adapters at inference time, without requiring prior domain knowledge. This design allows the model to leverage cross-domain similarities, making it especially robust in low-resource domain scenarios. Our experimental results on English–German, English–Marathi, and English–Tamil pairs across different domains for each pair show substantial improvements over their respective general-purpose APE baselines. To facilitate further research, we will release human-annotated domain labels for triplets in WMT22 English–Marathi, and WMT24 English–Tamil APE datasets and the code.